Local and Cloud Models
Supervertaler for memoQ can translate with a model running on your own computer, through Ollama or any OpenAI-compatible server such as LM Studio, as well as with Anthropic, OpenAI and Google. This page covers setting one up, what to expect from it, and what leaves your computer with each choice.
What leaves your computer
| Choice | Where your text goes |
|---|---|
| Ollama, with a model on your computer | Nowhere. The model runs locally and nothing is sent over the internet. |
Ollama cloud models (names ending in -cloud) | To Ollama’s servers. Supervertaler warns you in the settings and labels every translation “Ollama cloud” in memoQ. |
| OpenAI-compatible server | To whatever address you enter: your own computer, a server in your office, or a hosted service. |
| Anthropic, OpenAI, Google | To that provider, under its API terms for business customers. Anthropic’s, for example, do not use API data for training and delete it within 30 days. |
| Claude Desktop, through the MCP connector | To Anthropic, under the terms of the plan you are signed in with: the Team and Enterprise plans fall under Anthropic’s Commercial Terms, the personal Free, Pro and Max plans under its Consumer Terms. |
If a client requires that a document never leaves your computer, only a local model qualifies.
Setting up Ollama
- Install Ollama and download a model, for example from a command prompt:
ollama pull gemma4:26b-a4b. - In Supervertaler for memoQ → Settings → Translation settings, choose the provider Ollama.
- Leave Endpoint blank: blank means Ollama on this computer. Ollama needs no API key.
- Click Fetch list to see the models you have installed, and pick one.
- In memoQ’s own dialog, Test connection translates a short sentence to check that it all works.
For an OpenAI-compatible server, choose OpenAI-compatible and enter its address, including /v1, for example http://localhost:1234/v1 for LM Studio.
Context length: how much the model can read
Supervertaler sends each request with its instructions: your prompt, the memory bank and the segment, often 10,000 to 20,000 tokens with a memory bank. What limits how much the model reads:
- With Ollama, nothing to set. Supervertaler tells Ollama how much room each request needs, so Ollama’s own Settings → Context length makes no difference to Supervertaler. Before version 0.1.21 it did, and a request larger than it was silently cut.
- With an OpenAI-compatible server, its own context length, which in LM Studio you set when you load the model. 32k is a sensible value. Supervertaler checks every answer and refuses one that was made from part of the instructions, saying how large to set it.
- The model’s own limit, which no setting raises. Some models hold only 8,192 tokens (aya-expanse:8b, for example). Supervertaler asks Ollama for the model’s limit and refuses a request that cannot fit, at once, rather than after the model has read half of it. Switching off Send the memory bank to the model usually makes the request small enough.
Speed on a computer without a graphics card
A local model reads the instructions first and then writes the translation, and on an ordinary processor both are slow. On a fast desktop PC with no graphics card, the first segment of a document took 13 to 15 minutes, almost all of it reading about 15,000 tokens of instructions. After that Ollama reuses what it has read, and each segment takes from about half a minute to a few minutes, depending on the model.
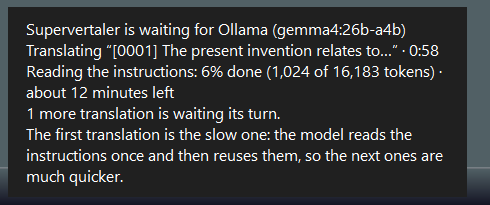
While you wait, Supervertaler shows a notice in memoQ’s corner: which segment the model is working on, how much of the instructions it has read, and roughly how long is left. If memoQ has stopped waiting by the time an answer arrives, the notice says so: click another segment and back to see it.
Ollama keeps the model loaded for four hours after the last segment, so a break does not mean reading all the instructions again. The model holds its memory meanwhile; quit Ollama to free it sooner. Supervertaler waits up to 30 minutes for each answer from a local model.
Before version 0.1.21 Ollama unloaded the model after five idle minutes, and the settings had a Keep the model loaded while Ollama runs box. That box is gone. If you ticked it, Ollama’s own OLLAMA_KEEP_ALIVE setting is left as it was and still applies to other programs that use Ollama.
A graphics card with enough memory changes the picture completely: the same models answer in seconds. A model of about 30 billion parameters needs around 24 GB of graphics memory.
Pre-translate with a slow model
Pre-translate sends ten segments at a time. On a computer without a graphics card one such batch can take many minutes, and memoQ’s own Cancel waits for the batch in progress to finish. Click Stop translating these segments on Supervertaler’s notice instead: the translation in progress is cancelled, everything still waiting is left untranslated, and memoQ’s Pre-translate finishes within seconds. The segments say why under the grid; translate them again later.
Some models, Gemma 4 and Qwen 3 for example, “think” before they answer unless told not to. Since version 0.1.21 Supervertaler tells them not to: one paragraph took 8 seconds instead of 213.
Parallel requests
Parallel requests is how many requests go to the model at once. It keeps two values, one for cloud providers and one for local servers, and the settings show whichever applies to the provider you have chosen.
- A model on your own computer: 1 is right. It works on one request at a time anyway.
- A cloud provider: 4 is a good start. Lower it if the provider says you are sending too many requests. Raising it above the number memoQ settled on when your MT settings were created (usually 4) makes no difference, because memoQ never sends more at once.
Before version 0.1.20 the cloud value had no effect at all.
What quality to expect
We tested this on a published Dutch patent, comparing a model you can run locally (Gemma 4 31B) with Claude Opus 5.5 and with the official English translation. In short:
- A model of 30 billion parameters writes fluent, mostly accurate patent English, but its terminology drifts: the same component got different names in different parts of the document, and the claim set came out inconsistent. Plan on a thorough post-edit.
- Smaller models (7 to 8 billion parameters) are not good enough for patent work. They produced invented words and grammar errors.
- House rules in SuperMemory make a large difference. Six Dutch patent conventions the model had been getting wrong were added to the shared memory bank, one line each, and the model applied all six on the next run. See SuperMemory memory banks.
- Claude Opus 5.5 stayed consistent from start to finish and flagged problems in the source text itself.
If you also use Supervertaler for Trados, SuperBench runs this kind of comparison on your own document, with a fourth model judging the translations blind.
The full test, with every paragraph side by side, is on supervertaler.com: Can a local AI model translate a patent?